Technology
Why YieldWatchDog: fast yield analytics on clean, contextualized data
AI is changing how engineers work with data, but every model is only as good as the data it works on. YieldWatchDog delivers that data — complete, consistent and in context from wafer fab to final test — and the speed to work with it, for your whole engineering team.
Why YieldWatchDog
What sets YieldWatchDog apart
Six reasons that matter even more now that AI is part of the engineering toolbox.
Answers in seconds
Queries across years of history return in seconds, and new data is loaded automatically as it arrives. Engineers investigate instead of waiting.
Clean data in context
Probe, final test, PCM/WAT, defect, equipment and MES data in one consistent data model, linked to lots, wafers, tools and process steps.
AI on a solid foundation
AI has been part of YieldWatchDog since 2017: pattern classification, multivariate monitoring and the YWD AIssistant work directly on your data.
Built for engineering teams
Engineers share views and reports with a click, comment on lots and receive the notifications that concern them.
Open REST API
Your own AI models and your other tools work with the same clean, contextualized data through the REST API.
Your data stays with you
YieldWatchDog runs on your own servers. With a local AI model, your data never has to leave your network.
Speed
High performance at full-fab data volumes
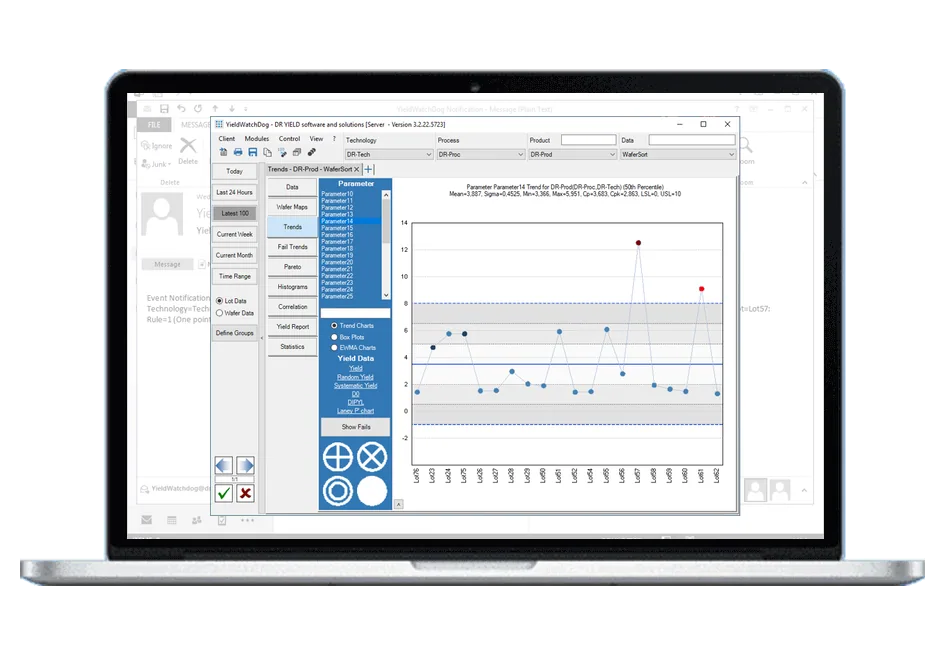
Yield analysis is iterative: every answer raises the next question. YieldWatchDog is built so that engineers do not wait between those questions — queries across years of history return in seconds, whether you collect gigabytes or terabytes.
All data sources are integrated into one large-scale, highly compressed database. Parallel data importers and automatic data partitioning allow you to scale the YieldWatchDog solution to match your requirements: new lots are loaded automatically as they arrive, and each query reads only the time periods it needs.
With the YieldWatchDog software, Inova now has a tool that is capable of parallel production data processing, enabling the rapid load and analysis of large amounts of information. This ensures a continuous delivery of products with the highest quality.
Data
Clean, contextualized data as the foundation
Every AI model, and every engineer, is only as good as the data they work with. In semiconductor manufacturing, a value means little without its context: which lot and wafer it belongs to, which tools and process steps the material passed through, which test insertion produced it.
YieldWatchDog loads probe, final test, PCM/WAT, defect, equipment and MES data into one consistent data model and keeps that context with every value. Our data integration specialists write the loaders for your formats, so the data arrives complete and consistent. The result is a sound foundation for any AI: YieldWatchDog’s own, or the tools you connect through its REST API.
- Probe
- Final test
- PCM/WAT
- Defect
- Equipment
- MES
One consistent data model
Linked to lots, wafers, tools and process steps
- YieldWatchDog’s own AI
- The tools you connect through its REST API
AI
AI that works on your yield data
AI part of YieldWatchDog since2017
AI has been part of YieldWatchDog since 2017. Machine learning detects and classifies wafers with conspicuous patterns for rapid material review and wafer disposition, and multivariate monitoring (T², PCA) catches problems that no single parameter shows.
The YWD AIssistant answers questions in plain language about the wafer maps, trends and charts you have open. It runs on the model you choose, including your own inference server, and its answers end with buttons that open the matching view, so engineers can check what the AI says against the data.
Meet the YWD AIssistant →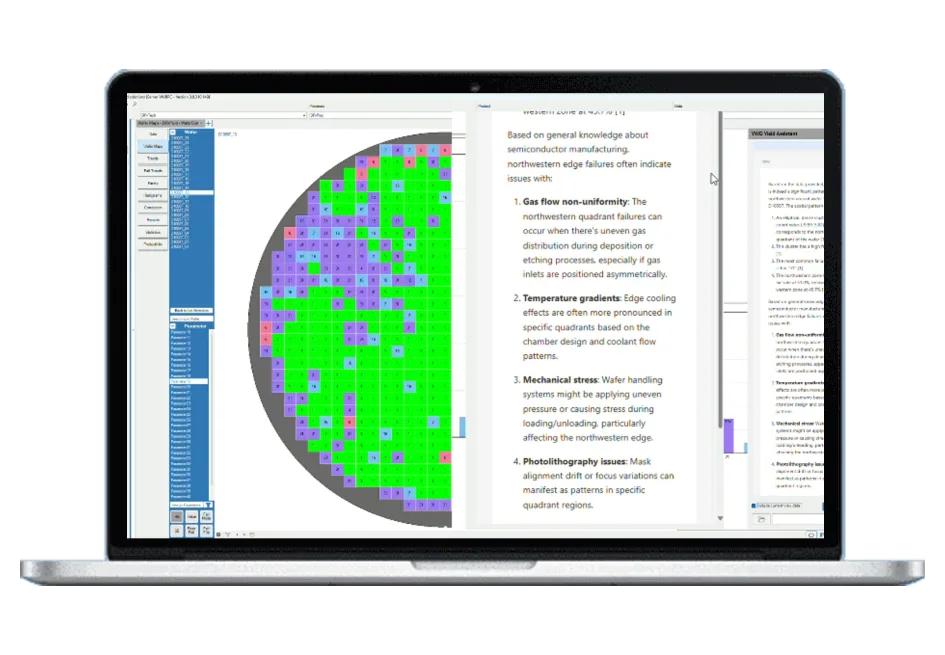
Teamwork
A platform for engineering teams
Yield problems are solved by teams: process, test, product and quality engineers looking at the same data from different angles. YieldWatchDog gives them one shared environment, with concurrent access in every edition and permissions for each user.
In the Sharing Center, engineers share views and reports with selected colleagues. A share code, sent in Microsoft Teams for example, opens the same view for a colleague instantly. Comments on lots are visible to the whole team and can be searched, and notifications reach the people responsible for a parameter or a tool.
- Share views and reports
- Comments on lots
- Notifications
Integration
Open to your other tools
YieldWatchDog does not lock your data away. Through its REST API, other applications work with the same clean, contextualized data: your own AI models and data science tools as well as your other in-house applications.
Your data is integrated and cleaned once, in YieldWatchDog, and every tool that needs it builds on the same foundation.
- Your own AI models
- Data science tools
- In-house applications
Deployment
Your data stays in your hands
YieldWatchDog is installed entirely within your company, on your own hardware, or on a cloud server if you prefer and have the network bandwidth. Your yield data does not have to leave your network: even the YWD AIssistant can run with a local model on the YieldWatchDog server or on your own inference server.
- Your own hardware
- A cloud server
- A local AI model
FAQ
Frequently asked questions
Why do we still need YieldWatchDog when AI tools can analyze data?
Because AI tools are only as good as the data they work on, and they do not do the work of getting that data right. In semiconductor manufacturing, data comes from many sources in many formats: probe and final test results, PCM/WAT, defect inspection, equipment and MES data. YieldWatchDog loads all of it into one consistent data model and keeps every value linked to its lot, wafer, tool and process step — the context an AI model needs to give correct answers. On this foundation, YieldWatchDog adds what engineers need every day: queries across years of history in seconds, established statistical methods such as SPC rules, Part Average Testing and multivariate monitoring, and AI that works directly on the data, including the YWD AIssistant. Engineering teams share views and reports, and through the REST API your own AI models and other tools work with the same data. AI does not make this foundation unnecessary; it makes it more important.
What should I do if our current yield software is too slow, obsolete or unable to scale with our business growth?
Many of our customers came to us after working with another platform. You can start with a low-cost trial installation using your own data before you decide anything: our experts write the loaders and parsers for your data during the trial, provide training and answer questions, so you see your own lots, wafers and tools in YieldWatchDog. The software is built to process huge amounts of data quickly and has been in use for many years in some of the largest front-end and back-end semiconductor fabs; the Ultimate edition adds massively parallel data import and multiple servers. Licensing is time-based — monthly, quarterly or yearly — with no large upfront investment. YieldWatchDog is vendor-independent — it works from whatever equipment and process data your fab already produces — and you reach the people who build and support the software directly, not a ticket queue.
How does YieldWatchDog handle massive amounts of data?
YieldWatchDog is implemented on a reliable, modern platform that’s capable of processing huge amounts of data quickly and efficiently. The software has been used for many years in some of the largest front end and back end semiconductor fabs and offers a proven solution for handling massive amounts of semiconductor manufacturing and test data.
What are the system requirements?
YieldWatchDog needs a Windows Server, physical or virtual, and runs on every Windows Server version that Microsoft supports. We define your hardware requirements once we know your data volume and throughput. The YieldWatchDog clients run on any version of Windows currently supported by Microsoft.
How is YieldWatchDog installed? Is it a hosted service? Can it run in the cloud?
We provide server and client software that is installed entirely within your company, on your own hardware. To maintain the highest security and performance criteria, we recommend a local installation of YieldWatchDog. However, if your company prefers a cloud solution and has the necessary network bandwidth, it is also possible to host the software on a cloud server.